
Order and Returns Orchestration Without Chaos: One OMS Flow for Every Channel
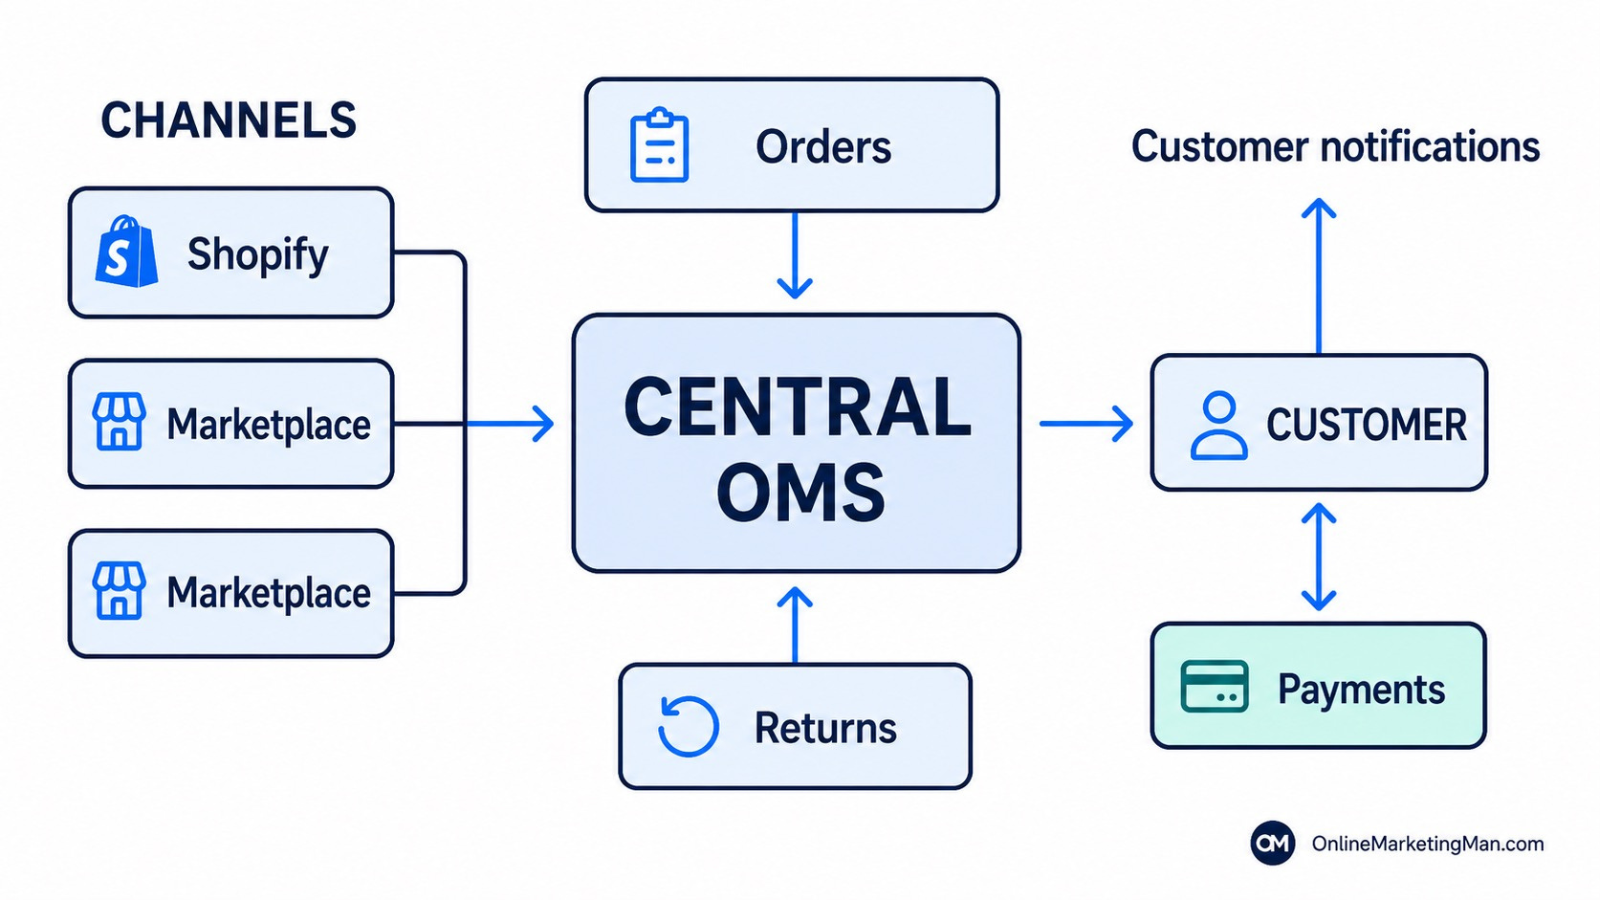
When orders from Shopify, marketplaces, and physical retail converge in one operational chain, complexity is not caused by volume alone. The real pressure comes from every channel using its own data model, statuses, service levels, and return rules. Duplicate tickets, delayed deliveries, inconsistent inventory information, and returns that remain administratively unresolved are therefore not isolated incidents. They show that the organization has connected multiple systems without centrally governing the decisions between them.
A lightweight Order Management System layer, or OMS layer, eliminates that fragmentation without replacing the ERP, commerce platform, or WMS. It normalizes events, applies central routing and return rules, and publishes decisions to every relevant system. The OMS therefore becomes an orchestration layer for speed, reliability, and commercial control rather than another administrative application. The goal is not more technology, but one traceable order and returns flow that supports scale without allowing complexity to grow faster than revenue.
Why ERP and Commerce Platforms Cannot Solve This Independently
ERP, commerce platforms, and fulfillment systems are each designed for a distinct core function. The ERP protects financial and administrative accuracy, Shopify or a marketplace records the commercial transaction, and the WMS or 3PL executes physical fulfillment. None of these systems automatically has a complete view of channel rules, available inventory locations, customer promises, and exceptions. When orchestration is forced into one of them, its core function becomes entangled with logic that needs to change continuously.
This creates three structural areas of tension. Channel data models use different fields and status definitions, fulfillment locations apply their own cutoff times and service levels, and return policies vary by market or sales platform. Without a central layer, these differences are resolved in separate integrations. The same rule is then maintained in several places, allowing a small change to produce unexpected effects on inventory, customer communication, and financial processing. Scale increases not only volume but the number of interdependencies.
Division of Responsibility Between Core Systems and the OMS Layer
The comparison below shows where the responsibility of existing systems ends and central orchestration begins. The OMS does not take over accounting, order creation, or warehouse execution. It connects these functions through one decision layer that normalizes orders, selects fulfillment, harmonizes statuses, and makes exceptions traceable. This separation prevents the OMS from becoming another monolithic system that introduces the same inflexibility the organization intended to eliminate.
| Component | Primary Responsibility | Missing Governance Function | Role of the OMS |
|---|---|---|---|
| ERP | Accounting, inventory administration, and financial processing | Channel normalization and dynamic fulfillment routing | Orchestrate decisions without duplicating financial source data |
| Shopify or marketplace | Order creation, payment, and commercial customer interaction | SLA monitoring and location selection across channels | Determine where and under which conditions fulfillment occurs |
| WMS or 3PL | Inventory allocation, picking, packing, and shipping | Central status and exception harmonization | Direct execution and publish uniform status updates |
| OMS layer | Normalization, routing, status synchronization, and returns orchestration | No replacement for financial or physical execution | Govern the complete order and returns chain |
This division of responsibility makes architecture decisions governable. The ERP remains the financial source, the commerce platform remains the sales channel, and the WMS remains responsible for warehouse execution. The OMS manages the transitions between these domains and records why an order was sent to a specific location, why a status changed, or why a return received different treatment. Rules can then be changed without jeopardizing core-system stability, while every exception remains investigable across the full chain.
The End-to-End Order Flow as a Governance Process
In a mature architecture, every order begins as an event. Webhooks from Shopify, marketplaces, or POS systems are not sent directly to a WMS but are first validated and normalized by the OMS. Channel-specific fields are translated into one internal order model, customer and address data is checked, and duplicate events are neutralized through idempotency keys. A consistent foundation is established before inventory is reserved or a fulfillment request is created.
The OMS then applies decision logic. Payment status, product restrictions, available inventory, cutoff times, shipping costs, country, service level, and possible margin impact are evaluated together. Only after all required conditions have been validated does the selected WMS or 3PL receive an executable pick-pack-ship instruction. Every status change is subsequently published as a new event to the commerce channel, customer communication, ERP, and analytics layer. One change therefore carries the same meaning and timestamp everywhere.
Returns follow the same architecture in the opposite direction. An RMA request is first tested against channel policies, the return window, product category, and customer status. Credit and inventory correction do not occur because a calendar date has been reached, but in response to verified receipt, inspection, and classification. This creates a closed chain in which outbound fulfillment and returns processing use the same identifiers, events, and audit log. The organization can see what happened and reconstruct which rule determined the outcome.
The Data Model as the Foundation for Scalability
Enterprise orchestration starts with a disciplined data model. Every order retains both the original channel identifier and an internal oms_order_id so the source and central processing remain traceable. Order lines explicitly record the SKU, variant, quantity, price, tax, bundle relationship, and applicable restrictions. Shipping method, carrier, priority, and promised delivery date cannot be free-text fields; they require values that rules and reports can interpret consistently. Discipline at this level prevents exceptions from disappearing into code or manual work instructions.
Idempotency is an operational control, not a technical refinement. Webhooks are offered again when a channel does not receive a timely acknowledgment, and network failures can cause the same order to arrive more than once. Without a unique idempotency key, one customer action may create duplicate reservations, duplicate shipments, and incorrect revenue recognition. The OMS must therefore recognize duplicate events and safely return the same outcome when earlier processing has already completed. That protects inventory, margin, and reputation at the same time.
An event store and a relational reporting layer then perform different functions. The event store preserves the chronological truth of every transition, while relational tables provide current status, financial impact, and operational aggregates. Combining both perspectives enables real-time operational control and retrospective governance of decisions. Retention policies, access rights, and data classification must be defined at design time because order and returns data contains personal information, payment-related details, and commercially sensitive patterns.
Idempotency is not a technical refinement, but risk control for inventory, customer promises, and revenue.
Orchestration Rules as a Strategic Instrument
The value of an OMS is not in forwarding orders, but in the quality of its routing and prioritization. Inventory availability is only one criterion alongside country, service level, logistics cost, expected delivery time, capacity, and margin. An order may technically be shippable from several locations while only one route is commercially optimal. Modeling this evaluation centrally turns fulfillment into a governable choice rather than an accidental consequence of whichever integration responds first.
Cutoff rules determine whether an order can still leave from distribution center A or should automatically move to distribution center B. Bundling rules can combine orders from the same customer when the delivery promise and product characteristics allow it, while split-shipment rules define when speed outweighs added freight cost. Priority may reflect the SLA, customer value, backorder status, or marketplace obligations. Every rule requires an explicit owner, version, and economic rationale.
Manageability is essential. Hard-coded rules make every commercial change dependent on a development cycle and increase the risk that old exceptions continue invisibly. Configuration through validated rule sets or a simple management interface gives operations controlled flexibility when approvals, testing, and rollback scenarios are built in. The organization can respond quickly to seasonal demand, carrier disruption, or market change without allowing local optimization to break the logic of the central chain.
Returns Orchestration as Margin Control
Returns are often treated as an administrative closing step even though they directly affect margin, inventory availability, and customer value. A return becomes financially governable only when the system distinguishes resale-ready stock, B-grade products, repairs, supplier claims, and full write-offs. Without central classification, these outcomes become mixed together and the organization cannot see where value is recovered or lost. The OMS therefore connects physical inspection to inventory action, credit processing, and reporting.
The same central logic must govern return windows, label generation, tracking, and exceptions across channels. This does not require every channel to offer identical terms, but it does require all differences to be documented as explicit rules. A marketplace may allow a longer return period than the proprietary store, while certain product categories may require additional inspection. Managing this variation in one model keeps execution consistent and allows finance to analyze the true returns impact by channel, SKU, and reason.
Financial and Operational Consequences by RMA Outcome
The classification below shows why one generic return status is insufficient. Each RMA outcome requires a different inventory action, financial treatment, and management question. The table is therefore not an administrative overview, but a basis for decisions about margin recovery, secondary sales, product quality, and supplier management. When inspection results are recorded directly in these categories, the OMS can activate the appropriate next action without additional interpretation.
| RMA Outcome | Inventory Action | Financial Effect | Strategic Meaning |
|---|---|---|---|
| Resale-ready | Return to available inventory after quality control | Substantial margin recovery | Efficient returns processing and rapid resale |
| B-grade | Separate inventory status and adapted sales channel | Partial loss of value | Secondary sales and controlled residual value |
| Repair or supplier claim | Block and assign to repair or claims process | Cost depends on recoverability | Insight into product and supplier quality |
| Write-off | Remove permanently from inventory and record the cause | Full loss | Structural issue and immediate improvement priority |
This structure makes returns data commercially useful. When outcomes are linked to the SKU, product variant, campaign, sales channel, and supplier, structural deviations appear before they disappear into aggregate figures. Marketing can adjust expectations in product content, procurement can address quality with suppliers, and finance can distinguish genuine margin recovery from a deferred write-off. Returns orchestration changes from cost registration into a feedback mechanism for the entire commercial chain.
Status Synchronization as Reputation Protection
A common problem in multichannel environments is the ghost status: a marketplace shows an order as shipped while the warehouse has not yet picked it, or the customer receives no delay notification because the status never leaves the WMS. These differences appear technical, but they directly affect the brand promise. Customers do not judge which system was responsible; they judge whether the information is accurate, timely, and consistent with the actual delivery.
The OMS must therefore govern a canonical status model that translates channel-specific terminology into one internal meaning. A WMS status such as allocated may not yet justify a customer message, while carrier acceptance provides a reliable shipping confirmation. Every transition includes its source, timestamp, order identifier, and reason so channels and notifications use the same truth. This approach reduces customer inquiries while preventing marketplace penalties and incorrect SLA reporting.
KPIs That Support Enterprise Decisions
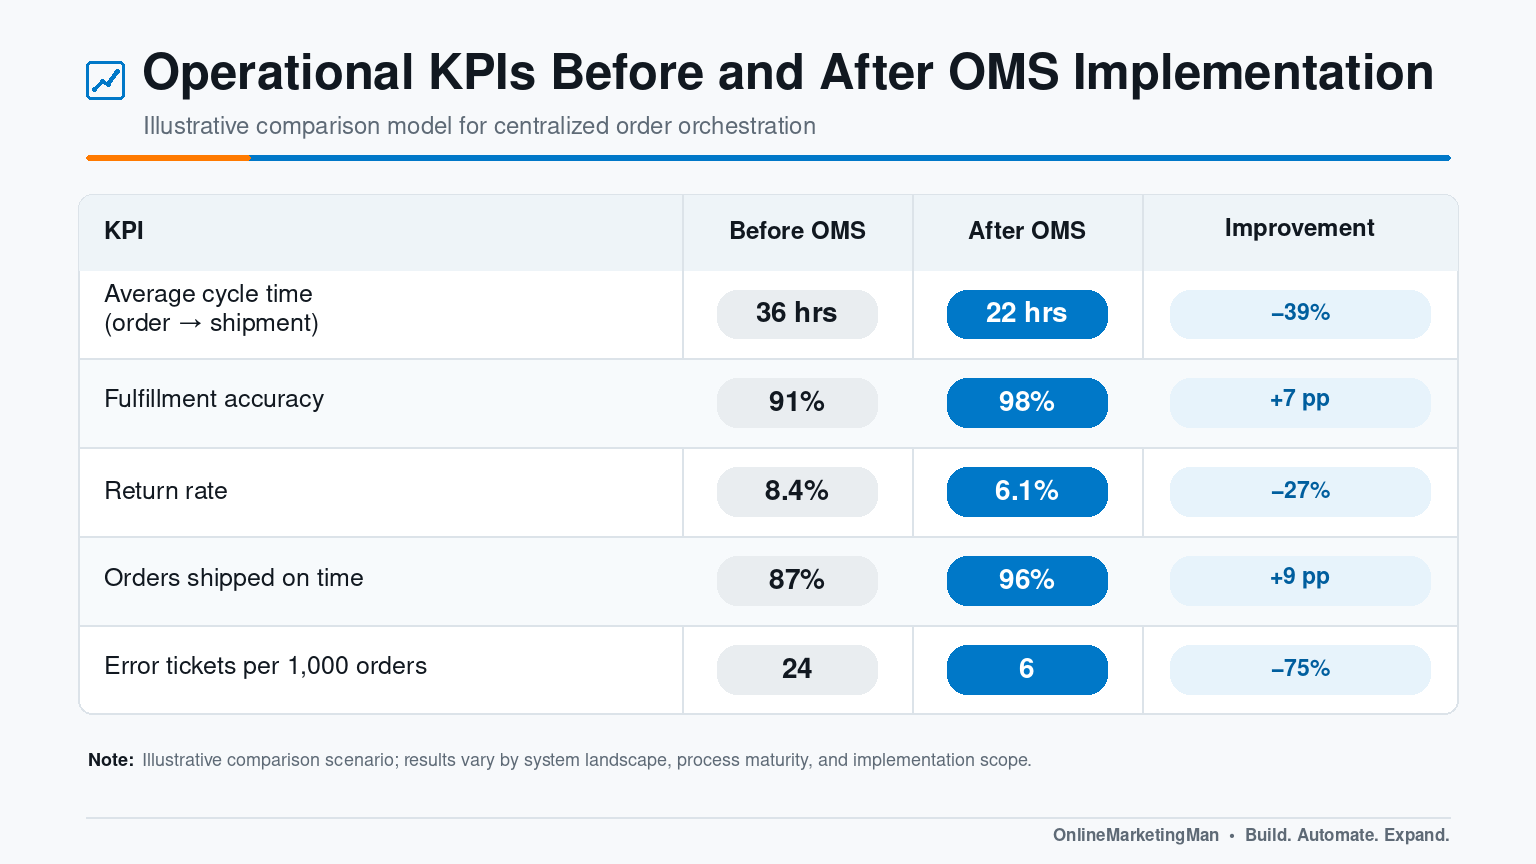
Total shipped orders and average cycle time provide insufficient insight into resilience. Averages hide the outliers that cause customer and margin damage under peak load. The p95 order cycle time therefore shows the period within which 95 percent of orders are processed and exposes performance outside the ideal midpoint. Combined with fulfillment accuracy and on-time shipping, it provides a more reliable view of process quality than volume alone.
Management Information for Resilience and Commercial Impact
The KPI set below connects operational performance to management questions. Every metric requires a fixed calculation method, data source, owner, and intervention threshold. Only then does a deviation prompt action instead of debate about the numbers. Values also become meaningful only in relation to each other: a faster flow is not an improvement when accuracy, return rate, or margin deteriorates at the same time.
| KPI | Management Significance | Example of a Targeted Intervention |
|---|---|---|
| p95 order cycle time | Measures resilience beyond the average | Adjust capacity or routing when delays become structural |
| Fulfillment accuracy | Shows the quality of picking, packing, and order data | Isolate error patterns by location, SKU, or process step |
| Return rate by channel and SKU | Detects expectation, product, or quality mismatch | Adjust content, assortment, or supplier terms |
| On-time shipping | Protects the customer promise and marketplace ranking | Recalibrate cutoff or carrier rules against actual performance |
| Cost per shipment | Exposes the direct margin impact of routing | Optimize bundling, location choice, or service mix |
The relationships between these metrics make central orchestration financially visible. Improvements in cycle time, fulfillment accuracy, and return rate may reinforce one another, but they can also correct seemingly positive results. A lower cost that produces more delays and returns is not an efficiency gain. Basing KPIs on the same order and event identifiers allows management to trace cause and effect and fund improvements that strengthen the full chain.
Architecture: Lightweight and Enterprise-Ready
An effective OMS architecture does not need to be heavy or monolithic. Webhooks provide the primary ingestion method, with controlled fallback polling for parties that cannot deliver reliable push events. A message broker such as SQS or RabbitMQ decouples receipt from processing so a temporary outage in a WMS, marketplace, or notification service does not immediately block the full chain. The architecture becomes resilient without requiring every system to understand all other components.
Small services for normalization, routing, RMA processing, status publication, and notifications keep responsibilities clearly bounded. This does not mean every function needs a separate microservice; boundaries should follow the pace of change and the operational risk. Routing rules, for example, change more often than financial posting logic and therefore deserve a separately governed domain. API contracts, version control, and schema validation prevent modularity from becoming a network of opaque dependencies.
Observability belongs in the architecture from the first implementation day. Structured logging, trace IDs, metrics, alerts, and a dead-letter queue reveal where an event stalls and which orders are affected. A DLQ is not a repository for forgotten exceptions, but a governed recovery flow with an owner, priority, and reprocessing procedure. Operations can iterate quickly without compromising reliability or accumulating operational debt outside management visibility.
Implementation in Ten Business Days: From Evidence to Control
A ten-business-day implementation is feasible when the scope is deliberately limited to one demonstrable end-to-end flow. The goal is not to automate every channel, return type, and exception in two weeks, but to prove the core architecture operationally. One store, one marketplace, and one WMS or 3PL are sufficient to test normalization, idempotency, routing, status publication, and observability under realistic conditions. The selected use case must still be representative enough to expose relevant risks.
Execution is divided into four controlled work blocks. Each block produces a tangible technical outcome, an operational validation, and an explicit decision point before the next component begins. Dependencies remain visible, and the team can resolve deviations within the phase where they originate instead of discovering them during the final go-live:
- Business days one and two define the canonical data model, identifiers, idempotency, and API contracts, including test events for regular orders, duplicates, and incomplete channel data.
- Business days three through five connect ingestion, the broker, and routing to one fulfillment provider, then validate cutoff rules, error handling, and status transitions in a controlled test environment.
- Business days six through eight configure status write-back, customer notifications, dashboards, and one representative RMA type so outbound and returns events operate in the same traceable chain.
- Business days nine and ten test edge cases and peak load in shadow mode, review the operational results, and only then activate controlled write permissions for each process stage.
Shadow mode prevents technical validation from creating immediate operational consequences. Every event is processed, decisions are logged, and expected outcomes are compared with the existing operation, but the OMS does not yet write back actively. Differences are classified as model, data, or process errors and resolved first. The transition to active processing then takes place by flow, with a rollback scenario, clear owners, and predefined acceptance criteria. This phased approach maximizes learning without using the live operation as a test environment.
Common Mistakes in OMS Implementations
The first mistake is centralizing all orchestration logic in the ERP. This makes a financial core system dependent on rules that must change quickly and creates long release cycles for operational adjustments. The second mistake is adding idempotency only after the first duplicate transaction. At that point, order identity, compensation rules, and recovery procedures are often already distributed across multiple systems. Both choices increase technical debt precisely where reliability matters most.
A third mistake is the absence of mature error handling. Without a dead-letter queue, traceability, and a clear operational owner, exceptions disappear into logs or are corrected manually outside the system. That may repair one order but destroys the audit trail and prevents structural learning. Hard-coded business rules without a version, rationale, or rollback option are equally problematic. The organization cannot reconstruct which rule made a decision and becomes dependent on specialized IT capacity for every change.
Finally, customer communication is often added at the end as though it were separate from fulfillment. The operation may publish internal statuses, but the customer receives information too late, too infrequently, or inconsistently. Proactive ETA communication, consistent channel statuses, and context for customer service must be part of the same event architecture from the beginning. A technically correct order flow becomes operationally mature only when the customer promise is demonstrably governed as well.
Central Governance as a Requirement for Scale
Multichannel fulfillment does not become ungovernable because of the number of channels, but because shared logic is missing. As long as systems operate beside one another, differences emerge in data, routing, status, and returns processing that become visible only under pressure. An OMS layer changes that environment not by replacing core systems, but by normalizing and tracing the decisions between them centrally. Operations shifts from resolving incidents to managing exceptions deliberately.
This governance requires shared ownership. Operations defines execution and recovery processes, IT protects architecture and reliability, finance defines financial truth and margin impact, customer service protects the customer promise, and commerce owners document channel requirements. Governance prevents each domain from optimizing locally while the overall chain performs worse. Decision rights, the change process, and KPI definitions must therefore be as explicit as API contracts and data models.
Multichannel complexity is not caused by volume, but by missing governance over data, decisions, and exceptions.
From Operational Complexity to Governable Growth
An enterprise-grade OMS program is not evaluated by the number of systems connected, but by the quality of the decisions the chain continues to make under pressure. Orders must retain one identity, routing must be explainable, return outcomes must be processed financially, and every status must carry the same meaning for the customer and the operation. When those conditions are met, volume can increase without remediation, error risk, and dependence on individual knowledge growing proportionally.
Implementation should therefore begin small, but the design must not be temporary. The first channel and fulfillment provider prove the data model, event architecture, observability, and governance that will later be reused for other markets and labels. Every subsequent connection follows the same contracts and control points, while only channel-specific rules are added. The system grows by repeating a proven pattern rather than accumulating exceptions.
The OMS also remains a governed product after go-live. KPIs, return reasons, dead-letter events, and manual overrides show where rules, data, or processes are insufficient. A fixed improvement process translates these signals into hypotheses, controlled changes, and measurable outcomes. Operational knowledge is no longer stored only in people or incident tickets, but returned to the architecture that supports future decisions.
The ultimate gain is greater than faster order processing. Central order and returns orchestration protects margin, makes customer promises more reliable, and gives management insight into the economic consequences of operational choices. Scale no longer means forcing increasing volume through the same fragmented chain, but creating a structure that can bring new channels, markets, and fulfillment partners under the same control. That is the difference between connected systems and a genuinely governable multichannel operation.
FAQ – Frequently Asked Questions
1. Do I need an expensive OMS package?
No. Start with a light service layer + queue; growth path to enterprise can be later.
2. What if my 3PL does not have an API?
Use SFTP jobs with status polling and mapping; still run events through OMS.
3. How do I avoid duplicate orders?
Idempotency keys + event store + retries with back-off.
4. When to credit on return?
Event-driven after inspection; not by calendar date.
5. What does bundling provide?
Lower number of shipments, better on-time %, lower cost per order.
Related Articles on Strategy, Automation and Growth:
Inventory Synchronization
For Centralized
OMS Control

A centralized OMS architecture only functions reliably when inventory is synchronized in real time at variant level across all sales channels. Without this synchronization, overselling, stock conflicts, and operational disruptions quickly emerge.
Feed Distribution
And Channel Mapping
Across Marketplaces

Efficient order processing requires structured product data and consistent channel mapping. A single catalog feeding multiple marketplaces ensures every sales channel receives accurate product information without operational friction.
From Single Store
To Ecommerce
Portfolio Architecture

Order and return orchestration becomes the operational backbone of a scalable ecommerce portfolio. It enables multiple stores to grow under centralized control while preventing fragmentation of processes and data.
OnlineMarketingMan
Build. Automate. Expand.