
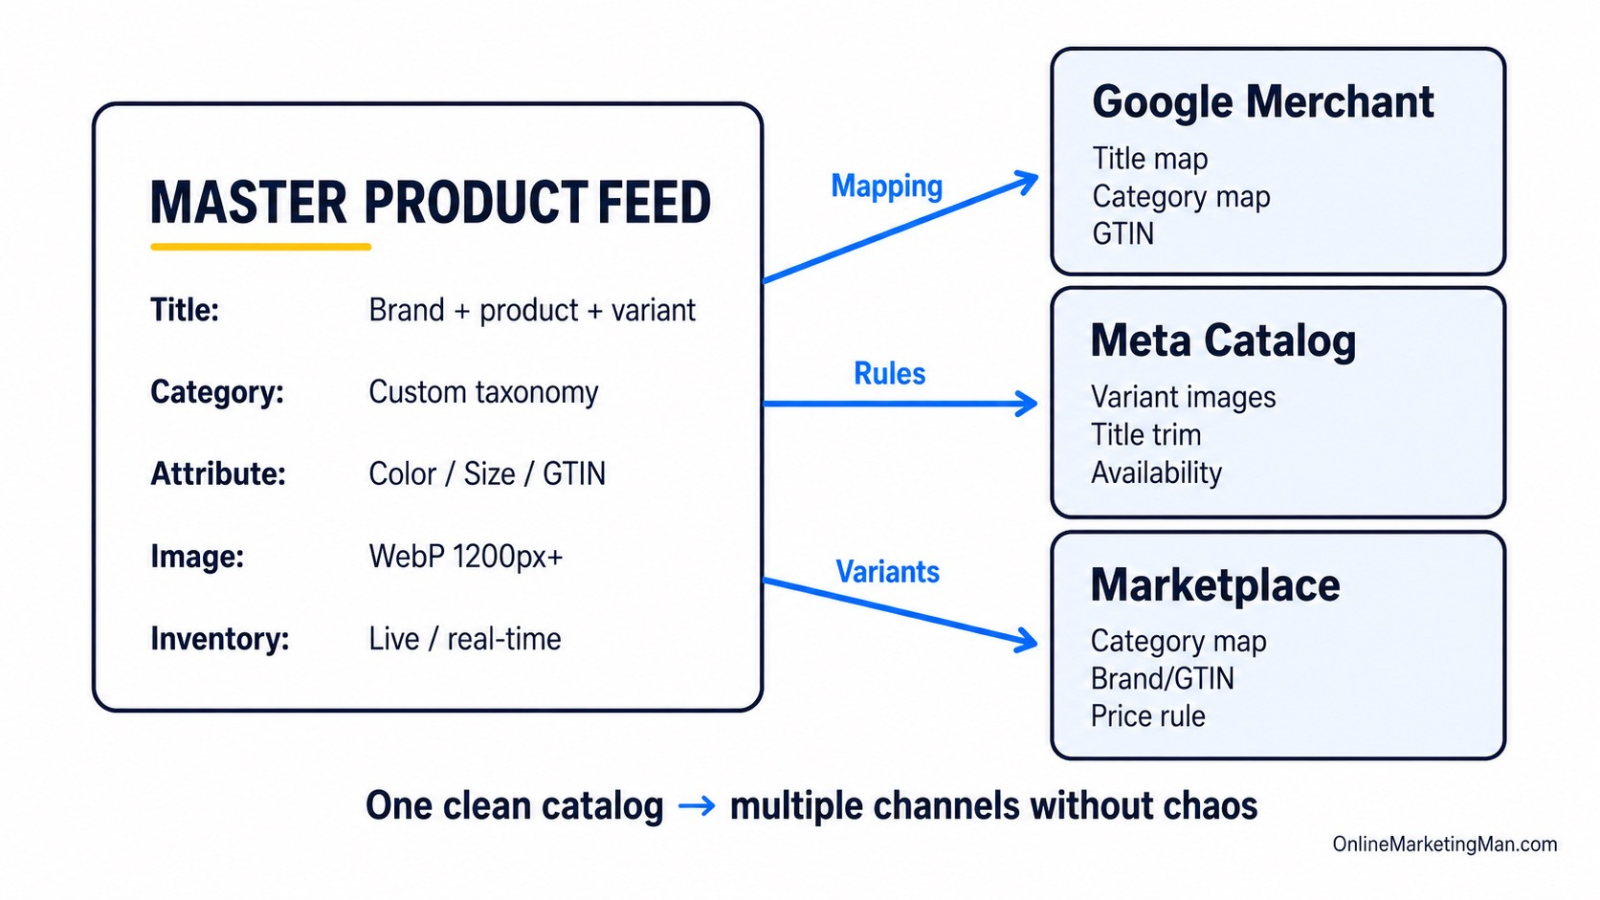
Feed Distribution and Channel Mapping: One Catalog, Multiple Channels
E-commerce growth is no longer determined by the strength of a single channel, but by the extent to which organizations can distribute product data consistently and under control across a fragmented digital landscape. The customer journey no longer moves linearly from orientation to purchase, but develops through a series of interactions across search engines, marketplaces, and social platforms. In that reality, the center of competition shifts from channel optimization toward data control. The channel itself does not determine the result; the quality and consistency of the data interpreted within that channel does.
Feed distribution is therefore not an operational task, but a structural layer within the commercial infrastructure. It determines how scalable an organization is, how quickly new products become visible, and how consistently the offer is presented across different platforms. Without central direction, complexity grows faster than revenue. With central direction, scale becomes a model for predictable growth instead of fragmentation.
From Channel Thinking to Distribution Logic
Many organizations still approach commerce from a channel-centric perspective. The online store functions as the primary source, marketplaces are added as supplementary sales channels, and advertising platforms are used to extend reach. Within this structure, product data is adjusted separately for each channel, creating several versions of the same information. Titles are rewritten, categories are changed manually, and prices are managed independently.
This approach remains workable while the assortment is limited, but breaks down as scale develops. As the number of variants increases and international markets are added, changes must be implemented in several places. Discrepancies begin to accumulate and eventually lead to a loss of control.
Distribution only becomes a problem when the same data is managed in several places.
Feed distribution changes this dynamic by working from one central catalog in which product data is cleaned, standardized, and enriched. From that source, data is distributed through a controlled layer in which rules determine how information is applied by channel. Optimization therefore takes place within the structure of the data itself rather than in the symptoms that become visible inside individual platforms.
Channel Mapping as an Interpretation Mechanism
Channel mapping forms the bridge between internal product data and external platform logic. It determines how data is interpreted within different ecosystems and therefore has a direct influence on visibility and performance. Within Amazon and Bol.com, visibility is strongly influenced by category classification and template fields. Google Merchant Center uses attributes and structured data to match search intent, while Meta relies heavily on visual context and engagement signals.
A uniform feed that is sent to these platforms without interpretation may meet the technical requirements, but often performs below its commercial potential. The reason is that every platform weighs the same data differently. Channel mapping bridges those differences by translating product data into the correct context for each channel without disrupting the central structure. This translation is based on four structural interventions that are applied consistently:
- Categories are aligned with the taxonomy of the platform.
- Attributes are prioritized according to visibility and relevance.
- Product titles are adapted to channel-specific limitations.
- Variant relationships are structured correctly according to platform logic.
Together, these interventions ensure that products are not merely technically available, but positioned competitively within the channel in which they appear. The product data therefore supports discoverability, filtering, classification, and relevance instead of functioning only as a mandatory platform input.
Distribution as a Direct Driver of Performance
When distribution and mapping are configured correctly, the impact on performance becomes direct and measurable. Products are not only distributed more broadly, but positioned more relevantly within the context in which they are shown. This affects both visibility and conversion.
The first impact occurs before the click. Products appear in more relevant search results because attributes and categories align more closely with search intent. Traffic quality improves, producing more stable conversion rates and more efficient use of advertising budgets across the complete channel mix.
Activation of new assortment also accelerates. Correctly structured feeds are processed more quickly and rejected less often, allowing products to go live faster across all channels. This shortens the time between product introduction and commercial activation. The combined impact produces three structural improvements:
- Stronger alignment with search intent and greater relevance before the click.
- Fewer rejections and faster product activation.
- More efficient use of media budget through higher conversion quality.
These effects do not result from campaign-level optimization, but from structural improvement of the underlying data. What is often underestimated is that distribution also determines the reliability of analysis. When product data is presented differently by channel, noise enters performance interpretation. Differences in conversion or visibility are then attributed to market or pricing factors, while the real cause lies in inconsistent attributes, categorization, or title structures. This leads to optimizations that address symptoms instead of structural causes.
A consistent distribution layer eliminates this distortion. When data is managed centrally and translated in a controlled way into channel-specific context, the organization gains a dataset that can be compared across channels. Patterns then become visible because of actual demand and behavior rather than differences in data interpretation.
Central distribution also shortens the feedback loop between change and effect. Adjustments to assortment, price, or presentation are transmitted directly to all channels, making the impact visible more quickly. This allows faster correction and reduces dependence on fragmented analysis. Distribution therefore functions not only as a transport layer for data, but as a foundation for reliable decision-making.
Architecture as the Foundation for Scale
Scalable feed distribution requires a clear separation between data, rules, and channel-specific requirements. Without that separation, fragmentation develops because every change must be interpreted again by channel. A structured architecture creates control by defining where data originates, where rules are applied, and where channel-specific variation is allowed.
| Component | Function | Effect |
|---|---|---|
| Master feed | Central product data | Consistency and reliability |
| Distribution layer | Rules and logic | Flexibility by channel |
| Validation | Monitoring and control | Stability and error reduction |
This structure makes it possible to implement a change once and roll it out under control across all channels. Scale therefore does not lead to a loss of oversight, but strengthens control because every channel continues to rely on the same governed foundation.
Implementation as a Controlled Process
Implementing a distribution model requires a sequence in which stability takes priority over speed. Many organizations try to activate several channels simultaneously, causing errors to multiply immediately. A controlled implementation begins with cleaning the master feed: product titles are standardized, attributes are completed, and variant structures are built consistently. Only once this foundation is stable are channel profiles configured and distribution rules activated.
This approach prevents errors from spreading across several channels and ensures that optimization begins from a controlled starting point. By creating structure first and adding scale afterward, complexity remains manageable, corrective work stays focused at the source, and later expansion does not reproduce the same data defects across every connected platform.
Practical Example: Distribution as a Structural Growth Accelerator
An international retailer with a broad assortment noticed that marketplace performance remained structurally below expectations despite increasing advertising investments. Internal analysis initially focused on campaign structure, bidding strategies, and targeting, but produced no lasting improvement. The assumption was that the problem concerned visibility or competitive pressure, while the actual cause lay deeper in the chain.
Further analysis showed that product data was managed in a fragmented way. Categories were applied inconsistently by channel, attributes were incomplete, and variants were not published as separate entities. Products were visible, but not positioned correctly. Filters did not align with the available variants, search results matched intent poorly, and algorithms interpreted low interaction as a signal of limited relevance.
After a central master feed and structured channel mapping were implemented, the situation changed fundamentally. Products were recategorized according to channel-specific taxonomies, attributes were completed and standardized, and variants were published as independent commercial units within a consistent parent structure. Within several weeks, products appeared more often in relevant search contexts and were filtered more accurately.
The impact was visible not only in reach, but especially in quality. Conversion stabilized without an increase in media budget, and dependence on advertising optimization declined. The problem had never been a lack of visibility, but a lack of correct interpretation of the data within the relevant context.
Variant Level as a Determining Factor in Conversion
In assortments where size, color, or execution matters, final conversion is not determined at product level, but at variant level. When variants are not visible separately within filters or advertisements, relevance is lost structurally. Users do not search for abstract products, but for specific configurations that match their needs.
When those configurations are not published separately, supply and demand fail to meet. Algorithms register low interaction and reduce visibility for the complete product, creating a downward spiral. What begins as a small data limitation develops into a structural performance problem.
A mature distribution model therefore treats variants as independent entities within a parent structure. Every variant has its own attributes, inventory status, and visual representation. This maximizes visibility within filters and improves matching with search intent. Conversion is not determined by the presence of a product, but by the discoverability of the correct variant.
Structural Errors and Their Cumulative Effect
Most feed-distribution problems do not result from technical limitations, but from a lack of structural discipline in data management. Small discrepancies may appear harmless in isolation, but together they reinforce one another and lead to structural performance loss across visibility, conversion, and operational efficiency.
Common errors develop gradually. Product titles contain insufficiently specific information and therefore align poorly with search intent. Category mapping is incomplete, placing products in less relevant segments. Real-time synchronization is missing, creating price and inventory discrepancies between systems. Images are reused without distinction between variants, reducing the effectiveness of filters.
Individually, these discrepancies appear limited, but collectively they undermine the commercial performance of the complete assortment. Performance loss rarely occurs suddenly; it grows as inconsistency increases. That makes the problem difficult to detect and even more difficult to correct without structural changes.
Governance as a Necessary Structure
Once distribution includes several channels, the challenge shifts from implementation toward control. Without clear governance, changes take place without oversight and discrepancies are often noticed only after performance has already declined, costs have increased, or several teams have already applied conflicting corrections.
Without governance, distribution becomes a collection of isolated interventions instead of a controlled system.
In this context, governance defines who is responsible for data quality, how changes are assessed, and within which boundaries optimization may take place. It prevents several teams from making simultaneous changes without central coordination, which would otherwise create inconsistency across platforms.
Monitoring is the operational counterpart of governance. It shows how data behaves across channels and where discrepancies develop. Connecting these insights to clear responsibilities creates an environment in which distribution remains stable and can be optimized continuously. The most important control points within this monitoring structure are:
- Coverage by channel compared with the complete assortment.
- Rejection rates by category and attribute.
- Completeness of variant structures within products.
- Consistency of price and inventory between systems.
Tracking these indicators structurally reveals where optimization is required and where risks are accumulating. In a mature environment, governance shifts from control toward steering. Data discrepancies are no longer viewed only as errors, but as signals of structural weaknesses in processes or architecture. When specific categories consistently show higher rejection rates, for example, that points to a mismatch between internal classification and external platform requirements. Without governance, these patterns remain unnoticed or are resolved ad hoc without structural improvement.
A structured approach makes these signals visible and traceable. By connecting changes to clear responsibilities and measurable effects, the organization can determine which interventions genuinely improve performance. This prevents optimizations from working against one another and creates consistency in decisions across channels.
Speed is crucial in this process. The shorter the time between detection and correction, the smaller the commercial impact of a discrepancy. In an environment without clear governance, minor data problems can accumulate for days, while a structured model enables immediate adjustment. In practice, this difference in response time determines how quickly organizations can react to changes in demand and competition.
Distribution as the Foundation for International Expansion
When feed distribution and channel mapping are established structurally, the role of channels changes fundamentally. They no longer function as separate sales channels, but as controlled extensions of one central catalog architecture. New markets can therefore be entered without rebuilding product data.
International expansion introduces new complexity through language, currency, and logistics. Without a central structure, every market is managed separately and the risk of inconsistency rises. With a structured distribution model, these variables can be added as layers within the same architecture, allowing scale without fragmentation.
Product information is therefore built once and then adapted by market within predefined boundaries. This creates speed in rollout without sacrificing control over data, interpretation, channel consistency, or the ability to compare commercial performance between countries and transfer successful optimizations from one market to another.
From Channel Management to Growth Strategy
When distribution is viewed as infrastructure instead of an export function, the role of channel management changes fundamentally. Channels are no longer optimized separately, but operate as components of one integrated system in which data is managed centrally and commercial variation is applied deliberately.
This makes it possible to experiment under control with pricing strategies, titles, and assortment choices without damaging the underlying structure. New channels can be added without rebuilding existing processes. Optimization shifts from reactive toward proactive because changes are implemented centrally and affect all channels immediately.
True scale does not lie in the number of channels added, but in the extent to which those channels are governed. Organizations that control distribution create a model in which growth does not produce complexity, but a predictable expansion of reach and revenue.
A central catalog forms the foundation. Channel mapping creates context. Governance and monitoring preserve stability. Together, these components create a distribution model that performs under current conditions and remains resilient as the organization grows without structural degradation of quality or control.
Scale Smarter Together?
Do you want to use one catalog across several channels without creating chaos? Read Why This Works for our pragmatic approach.
FAQ – Smart Marketing Automation OnlineMarketingMan
1) What do you mean by ‘marketing campaigns that run themselves’?
Campaigns automatically respond to customer behavior through triggers and segmentation. Examples include welcome and nurture flows, re-engagement campaigns and dynamic ads that continue running without manual intervention.
2) Which tools do you use for marketing automation?
Primarily Salesforce Marketing Cloud (including Account Engagement), complemented where appropriate by HubSpot or ActiveCampaign — often integrated with Shopify or WooCommerce.
3) Is marketing automation only suitable for large companies?
No. Start with foundational flows such as welcome journeys, abandoned cart recovery and lead nurturing, and expand as your data and results grow.
4) How much time can smart automation save?
Typically 40–60% less repetitive marketing work, including follow-ups, segmentation and reporting. The time gained can be reinvested in creative and strategic initiatives.
5) How do I decide what to automate first?
Start with repeatable, conversion-critical processes such as lead follow-ups, onboarding flows, back-in-stock notifications and post-purchase journeys. Launch with one flow and expand iteratively.
6) What if an automation triggers incorrectly?
Use test segments, clear if/then logic and sandbox environments. Log all events and configure alerts for failed sends or API errors.
7) How do you combine automation with personalization?
Customer data is the fuel: behavioral signals, purchase history and product interests. Deliver dynamic content and recommendations tailored to segments or personas.
8) Doesn’t automation feel impersonal?
Quite the opposite. Automation increases relevance by delivering the right message at the right moment, based on context. Always include clear opt-outs and preference controls.
9) How do I measure the ROI of marketing automation?
Track metrics such as conversion rate, CLV, retention and revenue per flow. Build dashboards (for example in GA4 or BI tools) and connect cost data to evaluate ROAS or ROI per journey.
10) Where should I start today?
Begin with one concrete nurture sequence or an abandoned cart flow. Document triggers, content and success metrics, test thorough
External authority links
Related Articles on Strategy, Automation and Growth
Product Data Quality
Normalization And
Catalog Enrichment

Channel mapping only works when product data is normalized and enriched so that every marketplace receives consistent, complete, and commercially optimized catalog information across all distribution channels.
Migrating Product
API Feeds Without
Breaking Catalog Logic
A stable feed distribution architecture requires carefully managed API feed migrations so product structures, attributes, and channel-specific catalog logic remain intact across every connected sales platform.
Dynamic Pricing
Optimization Across
All Sales Channels

Feed distribution becomes profitable when pricing rules and margin calculations are applied automatically per channel within a centralized catalog architecture that continuously optimizes revenue performance.
OnlineMarketingMan
Build. Automate. Expand.